Using gala-gopher
As a data collection module, gala-gopher provides OS-level monitoring capabilities, supports dynamic probe installation and uninstallation, and integrates third-party probes in a non-intrusive manner to quickly expand the monitoring scope.
This chapter describes how to deploy and use the gala-gopher service.
Installation
Mount the repo sources.
[oe-{version}]      # openEuler official released repository
name=oe{version}
baseurl=https://repo.openeuler.org/openEuler-{version}/everything/$basearch/
enabled=1
gpgcheck=0
priority=1

[oe-{version}:Epol] # openEuler:Epol official released repository
name=oe{version}_epol
baseurl=https://repo.openeuler.org/openEuler-{version}/EPOL/main/$basearch/
enabled=1
gpgcheck=0
priority=1
Install gala-gopher.
RPM installation applies to single-node observation scenarios without containers. openEuler 22.03 LTS SP1 or later is supported.
# yum install gala-gopher
Configuration
Configuration Description
The configuration file of gala-gopher is /etc/gala-gopher/gala-gopher.conf. The configuration items in the file are described as follows (the parts that do not need to be manually configured are not described):
The following configurations can be modified as required:
- global: gala-gopher global configuration information.
- log_file_name: gala-gopher log file name.
- log_level: gala-gopher log level (not supported currently)
- pin_path: path for storing the map shared by the eBPF probe. You are advised to retain the default value.
- metric: metric output mode.
- out_channel: metric output channel. The value can be web_server, logs, or kafka. If this parameter is left empty, the output channel is disabled.
- kafka_topic: topic configuration information if the output channel is Kafka.
- event: output mode of abnormal events.
- out_channel: event output channel. The value can be logs or kafka. If this parameter is left empty, the output channel is disabled.
- kafka_topic: topic configuration information if the output channel is Kafka.
- timeout: interval for reporting the same abnormal event
- desc_language: Language of the abnormal event description. Currently, the value can be zh_CN or en_US.
- meta: metadata output mode.
- out_channel: metadata output channel. The value can be logs or kafka. If this parameter is left empty, the output channel is disabled.
- kafka_topic: topic configuration information if the output channel is Kafka.
- ingress: configuration related to probe data reporting
- interval: not in use
- egress: configuration related to database reporting
- interval: not in use
- time_range: not in use
- imdb: cache specification configuration.
- max_tables_num: maximum number of cache tables. In the /opt/gala-gopher/meta directory, each meta corresponds to a table.
- max_records_num: maximum number of records in each cache table. Generally, each probe generates at least one observation record in an observation period.
- max_metrics_num: maximum number of metrics contained in each observation record.
- record_timeout: aging time of the cache table. If a record in the cache table is not updated within the aging time, the record is deleted. The unit is second.
- web_server: configuration of the web_server output channel.
- port: listening port.
- ssl_auth: whether to enable HTTPS encryption and authentication for the web server. The value can be on or off. You are advised to enable it in the production environment.
- private_key: absolute path of the server private key file used for web server HTTPS encryption. This parameter is mandatory when ssl_auth is on.
- cert_file: absolute path of the server certificate used for web server HTTPS encryption. This parameter is mandatory when ssl_auth is on.
- ca_file: absolute path of the CA certificate used by the web server to authenticate the client. This parameter is mandatory when ssl_auth is on.
- rest_api_server
- port: RestFul API listening port.
- ssl_auth: whether to enable HTTPS encryption and authentication for the RESTful API. The value can be on or off. You are advised to enable it in the production environment.
- private_key: absolute path of the server private key file used for RESTful API HTTPS encryption. This parameter is mandatory when ssl_auth is on.
- cert_file: absolute path of the server certificate used for RESTful API HTTPS encryption. This parameter is mandatory when ssl_auth is on.
- ca_file: absolute path of the CA certificate used by the RESTful API to authenticate the client. This parameter is mandatory when ssl_auth is on.
- kafka: configuration of the Kafka output channel.
- kafka_broker: IP address and port number of the Kafka server.
- batch_num_messages: number of messages sent in each batch.
- compression_codec: message compression type.
- queue_buffering_max_messages: maximum number of messages allowed in the producer buffer.
- queue_buffering_max_kbytes: maximum number of bytes allowed in the producer buffer.
- queue_buffering_max_ms: maximum time for a producer to wait for more messages to join a batch before sending the batch.
- logs: configuration of the logs output channel.
- metric_dir: path for storing metric data logs.
- event_dir: path for storing abnormal event data logs.
- meta_dir: metadata log path.
- debug_dir: path of gala-gopher run logs.
Configuration File Example
Select the data output channels.
metric =
{
    out_channel = "web_server";
    kafka_topic = "gala_gopher";
};

event =
{
    out_channel = "kafka";
    kafka_topic = "gala_gopher_event";
};

meta =
{
    out_channel = "kafka";
    kafka_topic = "gala_gopher_metadata";
};
Configure Kafka and Web Server.
web_server =
{
    port = 8888;
    ssl_auth = "off";
    private_key = "";
    cert_file = "";
    ca_file = "";
};

kafka =
{
    kafka_broker = "<Kafka server IP address>:9092";
};
Start
After the configuration is complete, start gala-gopher.
# systemctl start gala-gopher.service
Query the status of the gala-gopher service.
# systemctl status gala-gopher.service
If the following information is displayed, the service is started successfully: Check whether the enabled probe is started. If the probe thread does not exist, check the configuration file and gala-gopher run log file.
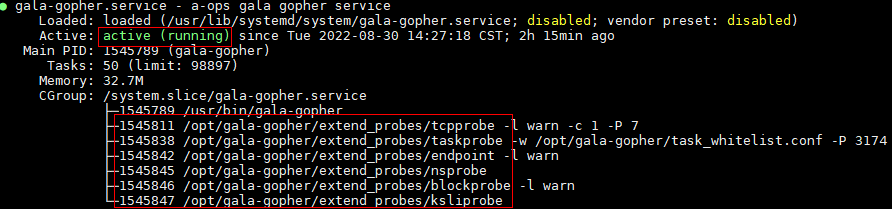
Note: The root permission is required for deploying and running gala-gopher.
Dynamic Configuration RESTful APIs
The port number of the web server is configurable (9999 by default). The URL format is http://[IP address of the gala-gopher node]:[Port number]/[Function]. For example, the URL of the flame graph is http://localhost:9999/flamegraph. (The following uses the flame graph as an example.)
Configuring the Probe Monitoring Scope
The probe is disabled by default. You can dynamically enable the probe and set the monitoring scope through the API. Take the flame graph as an example. Use the REST API to enable the oncpu, offcpu, and mem flame graph capabilities. The monitoring scope can be set by process ID, process name, container ID, or Pod.
The following is an example of enabling oncpu and offcpu information collection for a flame graph:
curl -X PUT http://localhost:9999/flamegraph --data-urlencode json='
{
    "cmd": {
        "bin": "/opt/gala-gopher/extend_probes/stackprobe",
        "check_cmd": "",
        "probe": [
            "oncpu",
            "offcpu"
        ]
    },
    "snoopers": {
        "proc_id": [
            101,
            102
        ],
        "proc_name": [
            {
                "comm": "app1",
                "cmdline": "",
                "debugging_dir": ""
            },
            {
                "comm": "app2",
                "cmdline": "",
                "debugging_dir": ""
            }
        ],
        "pod_id": [
            "pod1",
            "pod2"
        ],
        "container_id": [
            "container1",
            "container2"
        ]
    }
}'
The collection features are described as follows:
| Feature | Description | Collection Subitems | Supported Monitored Object Range | Startup File | Startup Condition |
|---|---|---|---|---|---|
| flamegraph | On-line performance flame graph observation capability | oncpu, offcpu, mem | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/stackprobe | NA |
| l7 | Application layer (layer 7) protocol observation capability | l7_bytes_metrics,l7_rpc_metrics,l7_rpc_trace | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/l7probe | NA |
| tcp | TCP exception and status observation capability | tcp_abnormal, tcp_rtt, tcp_windows, tcp_rate, tcp_srtt, tcp_sockbuf, tcp_stats,tcp_delay | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/tcpprobe | NA |
| socket | Socket (TCP/UDP) exception observation capability | tcp_socket, udp_socket | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/endpoint | NA |
| io | Block layer I/O observation capability | io_trace, io_err, io_count, page_cache | NA | /opt/gala-gopher/extend_probes/ioprobe | NA |
| proc | Process system call, I/O, DNS, VFS, and ioctl observation capabilities | proc_syscall, proc_fs, proc_io, proc_dns,proc_pagecache,proc_net,proc_offcpu,proc_ioctl | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/taskprobe | NA |
| jvm | JVM layer GC, thread, memory, and cache observation capabilities | NA | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/jvmprobe | NA |
| ksli | Redis performance SLI (access latency) observation capability | NA | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/ksliprobe | NA |
| postgre_sli | PostgreSQL database performance SLI (access latency) observation capability | NA | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/pgsliprobe | NA |
| opengauss_sli | openGauss access throughput observation capability | NA | [ip, port, dbname, user,password] | /opt/gala-gopher/extend_probes/pg_stat_probe.py | NA |
| dnsmasq | DNS session observation capability | NA | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/rabbitmq_probe.sh | NA |
| lvs | LVS session observation capability | NA | NA | /opt/gala-gopher/extend_probes/trace_lvs | lsmod|grep ip_vs| wc -l |
| nginx | Nginx layer 4/layer 7 session observation capability | NA | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/nginx_probe | NA |
| haproxy | HAProxy layer 4/layer 7 session observation capability | NA | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/trace_haproxy | NA |
| kafka | Kafka producer/consumer topic observation capability | NA | NA | /opt/gala-gopher/extend_probes/kafkaprobe | NA |
| baseinfo | Basic system information | cpu, mem, nic, disk, net, fs, proc, host, con | proc_id, proc_name, pod_id, container_id | system_infos | NA |
| virt | Virtualization management information | NA | NA | virtualized_infos | NA |
| tprofiling | Thread-level performance profiling observation capability | oncpu, syscall_file, syscall_net, syscall_lock, syscall_sched | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/tprofiling | NA |
| container | Container information | NA | proc_id, proc_name, container_id | /opt/gala-gopher/extend_probes/cadvisor_probe.py | NA |
| sermant | Java application layer 7 protocol observation capability. Currently, the dubbo protocol is supported. | l7_bytes_metrics, l7_rpc_metrics | proc_id, proc_name, pod_id, container_id | /opt/gala-gopher/extend_probes/sermant_probe.py | NA |
Configuring the Probe Monitoring Parameters
During probe running, you need to set some parameters, such as the sampling period and reporting period of the flame graph.
curl -X PUT http://localhost:9999/flamegraph --data-urlencode json='
{
    "params": {
        "report_period": 180,
        "sample_period": 180,
        "metrics_type": [
            "raw",
            "telemetry"
        ]
    }
}'
The detailed running parameters are as follows:
| Parameter | Description | Default Value & Range | Unit | Supported Features | Supported or Not |
|---|---|---|---|---|---|
| sample_period | Sampling period | 5000, [100~10000] | ms | io, tcp | Y |
| report_period | Report period | 60, [5~600] | s | ALL | Y |
| latency_thr | Latency report threshold | 0, [10~100000] | ms | tcp, io, proc, ksli | Y |
| offline_thr | Process offline report threshold | 0, [10~100000] | ms | proc | Y |
| drops_thr | Packet loss report threshold | 0, [10~100000] | package | tcp, nic | Y |
| res_lower_thr | Lower resource threshold | 0, [0~100] | percent | ALL | Y |
| res_upper_thr | Upper resource threshold | 0, [0~100] | percent | ALL | Y |
| report_event | Exception event report | 0, [0, 1] | - | ALL | Y |
| metrics_type | Telemetry metric report | "raw", ["raw", "telemetry"] | - | ALL | N |
| env | Environment type | "node", ["node", "container", "kubenet"] | - | ALL | N |
| l7_protocol | Layer 7 protocol scope | "",["http", "pgsql", "redis","mysql", "kafka", "mongo", "dns"] | - | l7 | Y |
| support_ssl | SSL observation support | 0, [0, 1] | - | l7 | Y |
| multi_instance | Independent flame graph for each process | 0, [0, 1] | - | flamegraph | Y |
| native_stack | Local language stack display (for Java processes) | 0, [0, 1] | - | flamegraph | Y |
| cluster_ip_backend | Cluster IP backend conversion | 0, [0, 1] | - | tcp, l7 | Y |
| pyroscope_server | IP address of the flame graph UI server | "localhost:4040" | - | flamegraph | Y |
| svg_period | Flame graph SVG file generation period | 180, [30, 600] | s | flamegraph | Y |
| perf_sample_period | Stack information collection period for oncpu flame graphs | 10, [10, 1000] | ms | flamegraph | Y |
| svg_dir | Directory for storing flame graph SVG files | "/var/log/gala-gopher/stacktrace" | - | flamegraph | Y |
| flame_dir | Directory for storing original stack information of flame graphs | "/var/log/gala-gopher/flamegraph" | - | flamegraph | Y |
| dev_name | Observed NIC/drive device name | "" | - | io, kafka, ksli, postgre_sli, baseinfo, tcp | Y |
| continuous_sampling | Continuous sampling | 0, [0, 1] | - | ksli | Y |
| elf_path | Observed executable file path | "" | - | baseinfo, nginx, haproxy, dnsmasq | Y |
| kafka_port | Observed Kafka port | 9092, [1, 65535] | - | kafka | Y |
| cadvisor_port | Started cAdvisor port | 8080, [1, 65535] | - | cadvisor | Y |
Starting and Stopping a Probe
curl -X PUT http://localhost:9999/flamegraph --data-urlencode json='
{
    "state": "running" // optional: running,stopped
}'
Restrictions
- The interface is stateless. The settings uploaded each time are the final running results of the probe, including the status, parameters, and monitoring scope.
- The monitored objects can be combined randomly, and the monitoring scope is the combination.
- The startup file must be authentic and valid.
- You can enable some or all subitems of a collection feature as required. However, you can only disable all subitems of a collection feature at once.
- The monitored object of OpenGauss is the database instance (ip/port/dbname/user/password).
- The interface can receive a maximum of 2048 bytes of data each time.
Obtaining the Probe Configurations and Running Status
curl -X GET http://localhost:9999/flamegraph
{
    "cmd": {
        "bin": "/opt/gala-gopher/extend_probes/stackprobe",
        "check_cmd": ""
        "probe": [
            "oncpu",
            "offcpu"
        ]
    },
    "snoopers": {
        "proc_id": [
            101,
            102
        ],
        "proc_name": [
            {
                "comm": "app1",
                "cmdline": "",
                "debugging_dir": ""
            },
            {
                "comm": "app2",
                "cmdline": "",
                "debugging_dir": ""
            }
        ],
        "pod_id": [
            "pod1",
            "pod2"
        ],
        "container_id": [
            "container1",
            "container2"
        ]
    },
    "params": {
        "report_period": 180,
        "sample_period": 180,
        "metrics_type": [
            "raw",
            "telemetry"
        ]
    },
    "state": "running"
}
Introduction to stackprobe
stackprobe generates performance flame graphs for cloud native environments.
Features
C/C++, Go, Rust, and Java applications can be observed.
The call stack supports container and process granularities. For processes in a container, the pod name and container name of the workload are prefixed with [Pod] and [Con] at the bottom of the call stack, respectively. A process name is prefixed with [
]. Threads and functions (methods) do not have prefixes. The flame graph in SVG format can be generated locally or the call stack data can be uploaded to the middleware.
Flame graphs can be generated or uploaded by multiple instances based on the process granularity.
For the flame graph of a Java process, both local and Java methods can be displayed.
Supports multiple types of flame graphs, such as oncpu, offcpu, and mem.
The sampling period can be customized.
Usage Instruction
Startup command example (basic): Use the default parameters to start the performance flame graph.
curl -X PUT http://localhost:9999/flamegraph -d json='{ "cmd": {"probe": ["oncpu"] }, "snoopers": {"proc_name": [{ "comm": "cadvisor"}] }, "state": "running"}'
Startup command example (advanced): Use custom parameters to start the performance flame graph. For details about the configurable parameters, see Configuring the Probe Monitoring Parameters.
curl -X PUT http://localhost:9999/flamegraph -d json='{ "cmd": { "check_cmd": "", "probe": ["oncpu", "offcpu", "mem"] }, "snoopers": { "proc_name": [{ "comm": "cadvisor", "cmdline": "", "debugging_dir": "" }, { "comm": "java", "cmdline": "", "debugging_dir": "" }] }, "params": { "perf_sample_period": 100, "svg_period": 300, "svg_dir": "/var/log/gala-gopher/stacktrace", "flame_dir": "/var/log/gala-gopher/flamegraph", "pyroscope_server": "localhost:4040", "multi_instance": 1, "native_stack": 0 }, "state": "running"}'
The main configuration items are described as follows:
Set the type of the flame graph to be enabled.
The probe parameter can be set to oncpu, offcpu, or mem, indicating the CPU occupation time, blocking time, and memory size of a process, respectively.
Example:
"probe": ["oncpu", "offcpu", "mem"]Set the period for generating a local flame graph SVG file.
The svg_period parameter can be set to an integer ranging from [30, 600]. The unit is second. The default value is 180.
Example:
"svg_period": 300Enable or disable stack information uploading to Pyroscope
Set the pyroscope_server parameter. The parameter value must contain addr and port. If the parameter is empty or the format is incorrect, the probe does not attempt to upload stack information.
The upload period is 30s.
Example:
"pyroscope_server": "localhost:4040"Set the call stack sampling period.
Set the perf_sample_period parameter. The unit is millisecond. The default value is 10. You can set this parameter to an integer ranging from [10, 1000]. This parameter is valid only for flame graphs of the oncpu type.
Example:
"perf_sample_period": 100Enable or disable flame graph generation for multiple instances
Set the multi_instance parameter. The value can be 0 or 1. The default value is 0. 0 indicates that the flame graphs of all processes are combined. 1 indicates that the flame graph of each process is generated separately.
Example:
"multi_instance": 1Enable or disable custom local call stack collection.
Set the native_stack parameter. The value can be 0 or 1. The default value is 0. This parameter is valid only for Java processes. 0 indicates that the JVM call stack is not collected. 1 indicates that the JVM call stack is collected.
Example:
"native_stack": 1Output: (left: "native_stack": 1; right: "native_stack": 0)

Implementation
1. User-Mode Program Logic
The program periodically (every 30s) converts the stack information reported by the kernel mode from an address to a symbol based on the symbol table. Then, the flamegraph plugin or pyroscope is used to convert the symbolic call stack into a flame graph.
Methods for obtaining the symbol tables for the code segment type are different.
Obtaining the kernel symbol table: Read /proc/kallsyms.
Obtaining the local language symbol table: Query the virtual memory mapping file (/proc/{pid}/maps) of the process to obtain the address mapping of each code segment in the process memory, and then use the libelf library to load the symbol table of the module corresponding to each code segment.
Obtaining the Java language symbol table:
Because Java methods do not statically map to the virtual address space of the process, other ways are used to obtain the symbolic Java call stack.
Method 1: perf
Load the JVM agent dynamic library to the Java process to trace JVM method compilation and loading events, obtain and record the mapping between memory addresses and Java symbols, and generate the symbol table of the Java process in real time. This method requires the Java process to enable the -XX:+PreserveFramePointer startup parameter. The advantage of this method is that the call stack of the JVM can be displayed in the flame graph, and the Java flame graph generated in this method can be displayed together with the flame graphs of other processes.
Method 2: JFR
Track various events and metrics of Java applications by dynamically turning on the JVM built-in analyzer JFR. To enable JFR, load the Java agent to the Java process. The Java agent invokes the JFR API. The advantage of this method is that the collection of Java method call stacks is more accurate and detailed.
The preceding two performance analysis methods for Java processes can be loaded in real time (without restarting the Java process) and have the advantage of low overhead. If the stackprobe startup parameters are "multi_instance": 1 and "native_stack": 0, stackprobe uses method 2 to generate Java process flame graphs. Otherwise, method 1 is used.
2. Kernel-Mode Program Logic
The kernel-mode logic is implemented based on eBPF. Different flame graph types correspond to different eBPF programs. The eBPF programs traverse the call stacks of the current user mode and kernel mode periodically or by triggering events, and report the call stacks to the user mode.
2.1 oncpu Flame Graph
Mount the sampling eBPF program to the PERF_COUNT_SW_CPU_CLOCK tracepoint for perf software events to periodically sample the call stack.
2.2 offcpu Flame Graph
Mount the sampling eBPF program to the tracepoint (sched_switch) for process scheduling. The sampling eBPF program records the time when the process is scheduled and the process ID. When the process is scheduled back, the call stack is sampled.
2.3 mem Flame Graph
Mount the sampling eBPF program to the tracepoint (page_fault_user) for page faults. When the event is triggered, the call stack is sampled.
3. Java Language Support
Main stackprobe process:
- The IPC message is received to obtain the Java process to be observed.
- Use the Java agent loading module to load the JVM agent program jvm_agent.so to the Java process to be observed (corresponding to Method 1) or JstackProbeAgent.jar (corresponding to Method 2).
- The main process of method 1 loads the java-symbols.bin file of the corresponding Java process for query during address conversion. The main process of method 2 loads the stacks-{flame_type}.txt file of the corresponding Java process, which can be directly used to generate a flame graph.
Java agent loading module
If a new Java process is found, copy the JVM agent program to the process space /proc/<pid>/root/tmp (because the agent program needs to be visible to the JVM in the container during attach).
Set the owner of the preceding directory and JVM agent program to be the same as that of the Java process to be observed.
Start the jvm_attach subprocess and transfers parameters related to the Java process to be observed.
JVM agent program
- jvm_agent.so: Registers the JVMTI callback function.
When the JVM loads a Java method or dynamically compiles a local method, the JVM invokes the callback function. The callback function writes the Java class name, method name, and corresponding memory address to the observed Java process space (/proc/<pid>/root/tmp/java-data-<pid>/java-symbols.bin).
- JstackProbeAgent.jar: Calls the JFR API.
Enable the JFR function for 30 seconds, convert the JFR statistics result to the stack format available for the flame graph, and export the result to the observed Java process space (/proc/<pid>/root/tmp/java-data-<pid>/stacks-<flame_type>.txt). For details, see Introduction to JstackProbe.
jvm_attach: Loads the JVM agent program to the JVM of the observed process in real time. For details, see sun.tools.attach.LinuxVirtualMachine and jattach in the JDK source code.
Set its own namespace. (When the JVM loads the agent, the namespace of the loading process must be the same as that of the observed process.)
Check whether the JVM attach listener is started (whether the UNIX socket file /proc/<pid>/root/tmp/.java_pid<pid> exists).
If the process is not started, create /proc/<pid>/cwd/.attach_pid<pid> and send the SIGQUIT signal to the JVM.
Connect to the UNIX socket.
If the read response is 0, the attach operation is successful.
The following figure shows the attach agent process.

Notes
- To obtain the best observation effect on Java applications, set the stackprobe startup option to "multi_instance": 1, "native_stack": 0 to enable JFR observation (JDK8u262+). Otherwise, stackprobe generates a Java flame graph using perf. In perf mode, enable the JVM option
XX:+PreserveFramePointer(JDK8 or later).
Constraints
- Hotspot JVM-based Java application observation is supported.
Introduction to tprofiling
tprofiling is an eBPF-based thread-level application performance diagnosis tool provided by gala-gopher. It uses the eBPF technology to observe key system performance events of threads and associate rich event content. In this way, the running status and key actions of threads are recorded in real time, helping users quickly identify application performance problems.
Features
From the perspective of the OS, a running application program consists of multiple processes, and each process consists of multiple running threads. tprofiling observes and records key actions (events) performed by these threads during thread running, and displays the actions in a time line on the front-end page. In this way, you can intuitively analyze the actions in a certain period of time, whether an action is performed on the CPU or blocked on a file or network operation. When a performance issue occurs in an application, you can analyze the execution sequence of key performance events of the corresponding thread to quickly demarcate and locate the issue.
Based on the implemented event observation scope, tProfiling can locate application performance issues in the following scenarios:
- File I/O time consumption and blocking
- Network I/O time consumption and blocking
- Lock contention
- Deadlock
As more types of events are supplemented and improved, tprofiling will be able to cover more types of application performance issue scenarios.
Event Observation Scope
Currently, tprofiling supports two types of system performance events: system call events and oncpu events.
System call events
Application performance issues are usually caused by system resource bottlenecks, such as high CPU usage and I/O resource waiting. Applications often access these system resources through system calls. Therefore, key system call events can be observed to identify time-consuming or blocked resource access operations.
For details about the observed system call events, see Supported System Call Events. The events include file operations (file), network operations (net), lock operations (lock), and scheduling operations (sched). Some of the observed system call events are as follows:
- File operations (file)
- read/write: Reading or writing drive files or network resources, which may be time-consuming and blocked.
- sync/fsync: Synchronizing files to drives. The thread is blocked until the synchronization is complete.
- Network operations (net)
- send/recv: Reading or writing network resources, which may be time-consuming and blocked.
- Lock operations (lock)
- futex: System call related to user-mode lock implementation. If futex is triggered, lock contention occurs and the thread may be blocked.
- Scheduling operations (sched): System call events that may change the thread status, such as CPU release, sleep, and waiting for other threads.
- nanosleep: The thread enters the sleep state.
- epoll_wait: The thread is waiting for the arrival of an I/O event. The thread is blocked before the event arrives.
oncpu events
The running state of a thread can be oncpu or offcpu according to whether the thread is running on the CPU. By observing the oncpu event of a thread, you can identify whether the thread is performing time-consuming CPU operations.
Event Information
Thread profiling events include the following information:
Event sources: thread ID, thread name, process ID, process name, container ID, container name, host ID, and host name of the event.
- thread.pid: ID of the thread to which the event belongs.
- thread.comm: name of the thread to which the event belongs.
- thread.tgid: ID of the process to which the event belongs.
- proc.name: name of the process to which the event belongs.
- container.id: ID of the container to which the event belongs.
- container.name: name of the container to which the event belongs.
- host.id: ID of the host to which the event belongs.
- host.name: name of the host to which the event belongs.
Event attributes: common event attributes and extended event attributes.
Common event attributes:
- event.name: event name.
- event.type: event type. Currently, oncpu, file, net, lock, and sched are supported.
- start_time: start time of the event or the first event in an aggregated event. For details about aggregated events, see Aggregated Events.
- end_time: event end time or the end time of the last event in an aggregated event.
- duration: event execution time. The value is (end_time - start_time).
- count: number of events that are aggregated.
Extended event attributes:
- func.stack: information about the function call stack of an event.
- file.path: file path of a file event.
- sock.conn: TCP connection information about a network event.
- futex.op: operation type of a futex system call event. The value can be wait or wake.
For details about the extended event attributes supported by different event types, see Supported System Call Events.
Event Output
As an extended eBPF probe program provided by gala-gopher, tprofiling sends generated system events to gala-gopher for processing. gala-gopher then outputs the events in the open source openTelemetry event format, and sends a message to the Kafka message queue in JSON format. The frontend can connect to Kafka to consume tprofiling events.
The following is the example output of a thread profiling event:
{
 "Timestamp": 1661088145000,
 "SeverityText": "INFO",
 "SeverityNumber": 9,
 "Body": "",
    "Resource": {
  "host.id": "",
        "host.name": "",
        "thread.pid": 10,
        "thread.tgid": 10,
        "thread.comm": "java",
        "proc.name": "xxx.jar",
        "container.id": "",
        "container.name": "",
 },
    "Attributes": {
        values: [
            {
                // common info
                "event.name": "read",
                "event.type": "file",
                "start_time": 1661088145000,
                "end_time": 1661088146000,
                "duration": 0.1,
                "count": 1,
                // extend info
                "func.stack": "read;",
                "file.path": "/test.txt"
            },
            {
                "event.name": "oncpu",
                "event.type": "oncpu",
                "start_time": 1661088146000,
                "end_time": 1661088147000,
                "duration": 0.1,
                "count": 1,
            }
        ]
 }
}
Field description:
- Timestamp: event point reported by the event.
- Resource: event source information.
- Attributes: event attribute information, which contains a values list. Each item in the list indicates a tprofiling event from the same source and contains the attribute information of the event.
Getting Started
Installation and Deployment
tprofiling is an extended eBPF probe program provided by gala-gopher. Therefore, you need to install and deploy gala-gopher before enabling tprofiling.
In addition, to use the tprofiling capability on the frontend user interface (UI), gala-ops sets up a UI demonstrating the tprofiling function based on the open source solution of Kafka + Logstash + Elasticsearch + Grafana. You can use the deployment tool provided by gala-ops for quick deployment.
Operating Architecture

Frontend software description:
- Kafka: open source message queue middleware used to receive and store tprofiling events collected by gala-gopher.
- Logstash: real-time open source log collection engine used to consume tprofiling events from Kafka, filter and convert the events, and send them to Elasticsearch.
- Elasticsearch: open distributed search and analysis engine used to store processed tprofiling events for Grafana query and visualization.
- Grafana: open source visualization tool used to query and visualize collected tprofiling events. You can use the tprofiling function on the UI provided by Grafana to analyze application performance issues.
Deploying the tprofiling Probe
You need to install gala-gopher first. For details about how to install and deploy gala-gopher, see the Gala-gopher Documentation. tprofiling events are sent to Kafka. Therefore, you need to configure the Kafka service address during deployment.
After installing and running gala-gopher, use the HTTP-based dynamic configuration interface provided by gala-gopher to start the tprofiling probe.
curl -X PUT http://<gopher-node-ip>:9999/tprofiling -d json='{"cmd": {"probe": ["oncpu", "syscall_file", "syscall_net", "syscall_sched", "syscall_lock"]}, "snoopers": {"proc_name": [{"comm": "java"}]}, "state": "running"}'
Parameter description:
: IP address of the node where gala-gopher is deployed. - probe: probe of cmd specifies the range of system events observed by the tprofiling probe. oncpu, syscall_file, syscall_net, syscall_sched and syscall_lock correspond to the oncpu event and system call events file, net, sched, and lock. You can choose tprofiling event types to observe.
- proc_name: proc_name of snoopers filters the names of the processes to be observed. You can also use the proc_id configuration item to filter the IDs of the processes to be observed. For details, see Dynamic Configuration RESTful APIs.
To disable the tprofiling probe, run the following command:
curl -X PUT http://<gopher-node-ip>:9999/tprofiling -d json='{"state": "stopped"}'
Deploying the Frontend Software
The software required for using the tprofiling function includes Kafka, Logstash, Elasticsearch, and Grafana. They are installed on the management node. You can use the deployment tool provided by gala-ops to quickly install and deploy them. For details, see the documents of gala.
On the management node, run the following command to obtain the deployment script and install middleware Kafka, Logstash, and Elasticsearch:
sh deploy.sh middleware -K <deployment node management IP address> -E <deployment node management IP address> -A -p
Run the following command to install Grafana:
sh deploy.sh grafana -P <Prometheus server address> -E <Elasticsearch server address>
Usage
After the deployment is complete, visit http://<deployment node Management IP address>:3000 and log in to Grafana to use A-Ops. The default username and password are admin.
After logging in to Grafana, find the dashboard named ThreadProfiling.

Click to access the frontend page of the tprofiling function.

Usage Examples
Case 1: Locating a Deadlock Issue

The preceding figure shows the thread profiling result of a deadlock demo process. According to the statistics of the process event execution time in the pie chart, the proportion of lock events (in gray) is high during this period. The lower part displays the thread profiling result of the entire process. The vertical axis displays the execution sequence of profiling events of different threads in the process. The java thread is the main thread and is always blocked. After executing some oncpu events and file events, the service threads LockThd1 and LockThd2 intermittently execute lock events for a long time. The lock event details (as shown in the following figure) shows that the futex system call event is triggered and the execution time is 60 seconds.

Based on the preceding observation, it can be found that the service threads LockThd1 and LockThd2 may be abnormal. The thread view shows the thread profiling results of the two service threads LockThd1 and LockThd2.
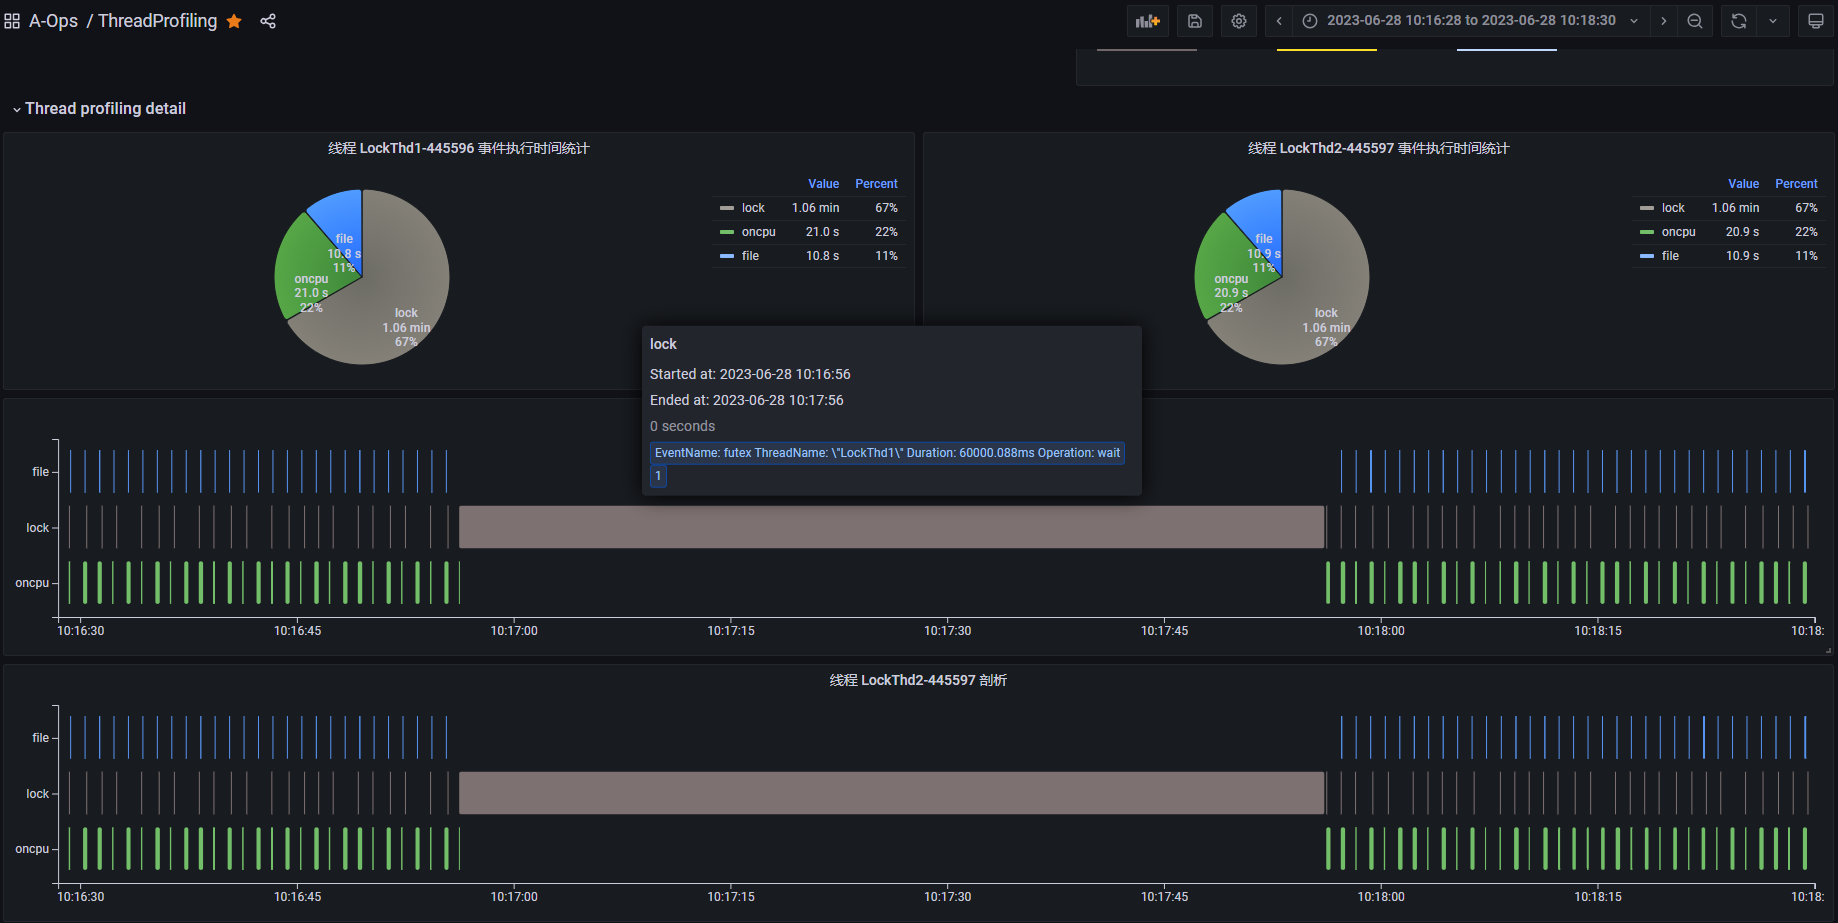
The preceding figure shows the profiling result of each thread. The vertical axis displays the execution sequence of different event types in the thread. As shown in the figure, threads LockThd1 and LockThd2 periodically execute oncpu events, including file events and lock events. However, at a certain moment (near 10:17:00), they simultaneously execute a futex event of the lock type for a long time, and no oncpu event occurs during this period, indicating that they enter the blocking state. futex is a system call related to user-mode lock implementation. If futex is triggered, lock contention occurs and threads may enter the blocking state.
Based on the preceding analysis, deadlocks may occur on threads LockThd1 and LockThd2.
Case 2: Lock Contention Issue Locating
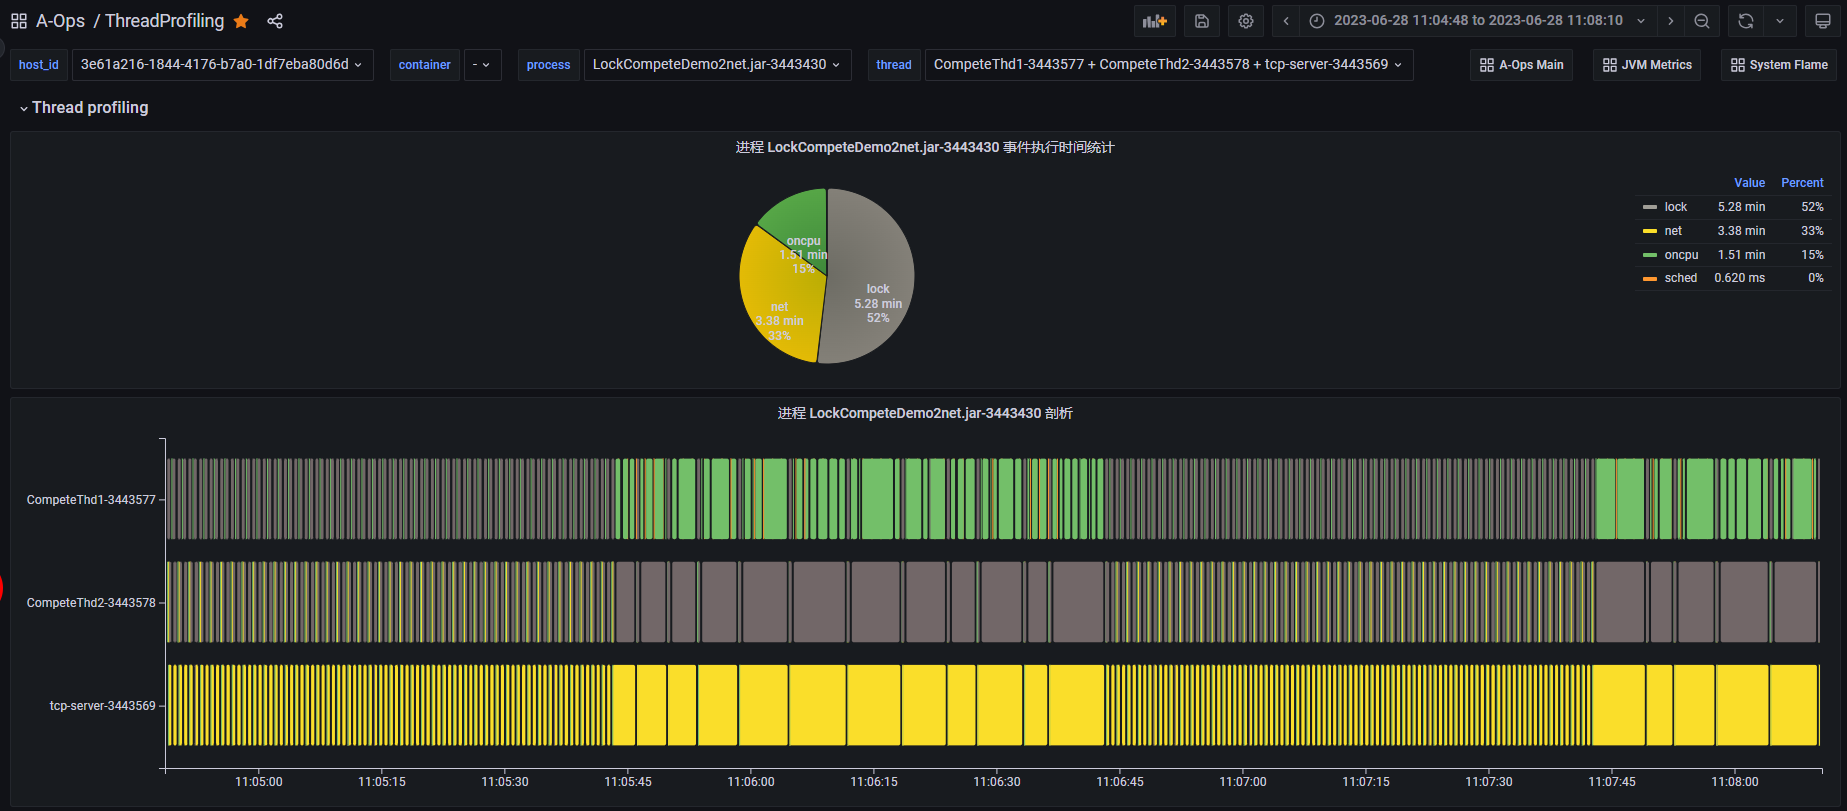
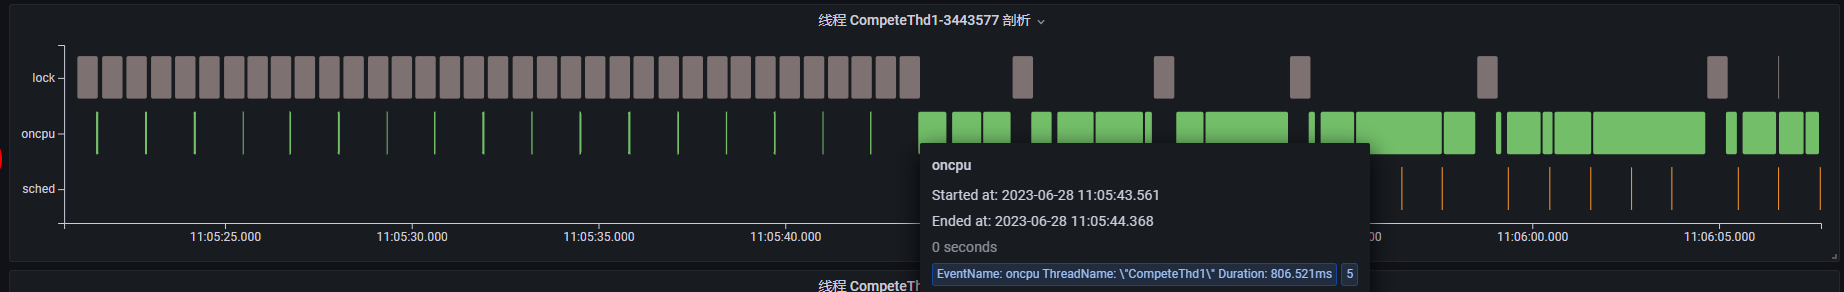
The preceding figure shows the running result of thread profiling of a lock contention demo process. As shown in the figure, the process executes three types of events: lock, net, and oncpu. The process contains three running service threads. From 11:05:45 to 11:06:45, the event execution time of the three service threads becomes long, which may indicate performance issues. Similarly, the thread view shows the thread profiling result of each thread. In addition, the time range can be narrowed down to a point near the time when an exception may occur.
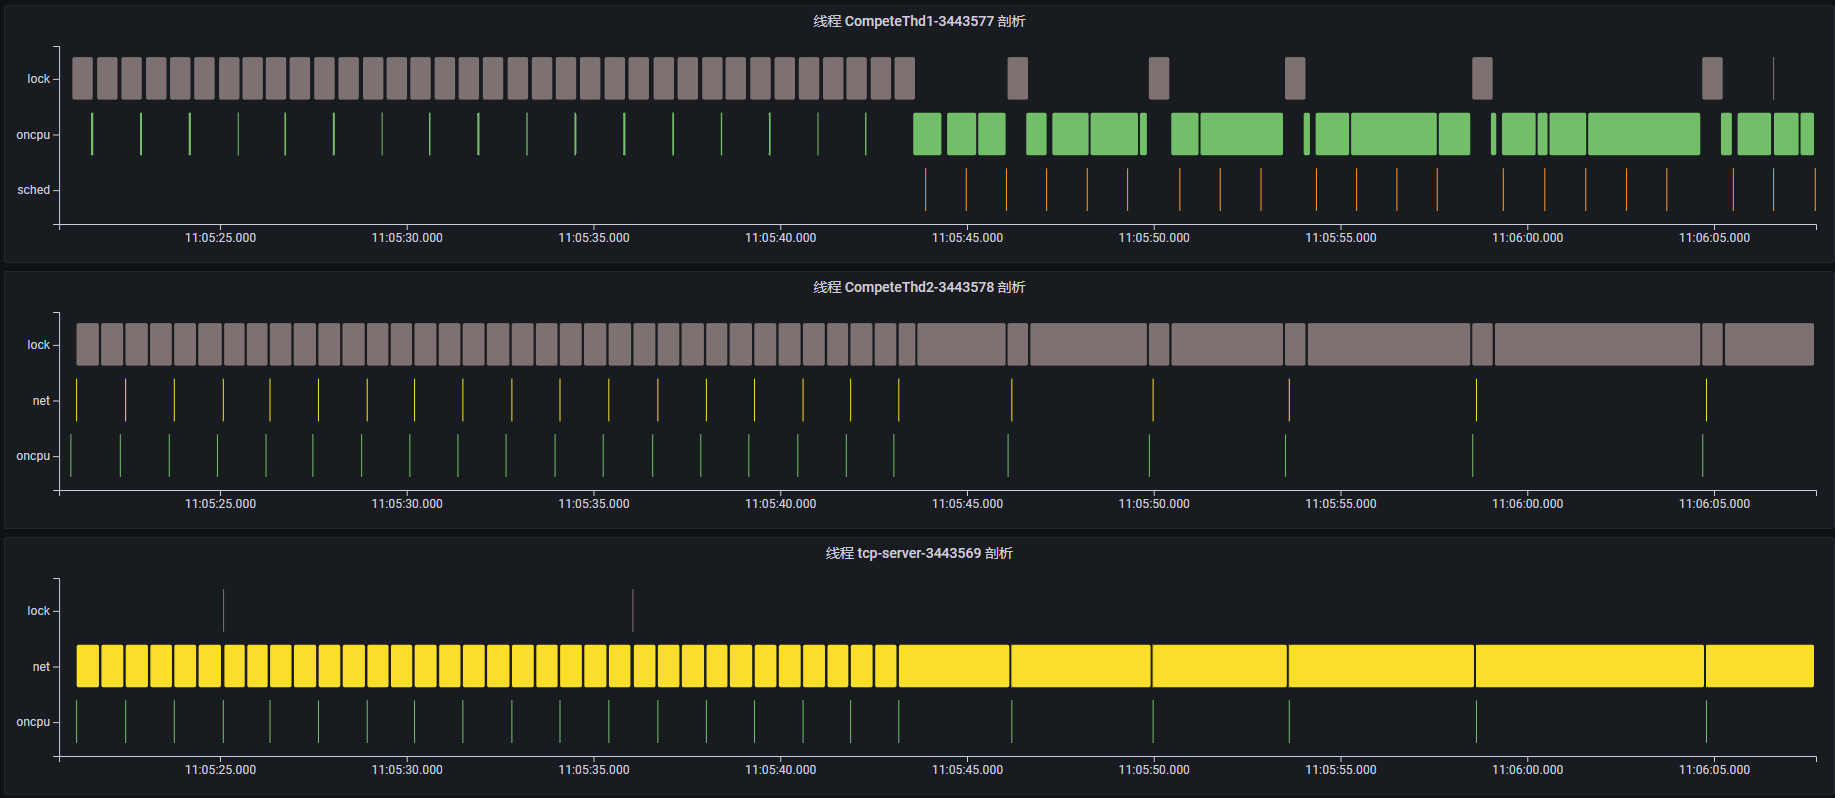
By viewing the event execution sequence of each thread, we may understand the functions that each thread is performing during this period.
Thread CompeteThd1: A short oncpu event is triggered at a interval to execute a computing task. However, a long oncpu event is triggered around 11:05:45, indicating that a time-consuming computing task is being executed.
Thread CompeteThd2: A short net event is triggered at a interval. The event details show that the thread is sending network messages using the write system call and the corresponding TCP connection information is displayed. At 11:05:45, the futex event is executed for a long time and enters the blocking state. In this case, the execution interval of the write network event is prolonged.


Thread tcp-server: The TCP server continuously reads requests sent by the client using the read system call. The read event execution time is prolonged around 11:05:45, indicating that the server is waiting for network requests.

Based on the preceding analysis, it can be found that each time thread CompeteThd1 performs a time-consuming oncpu operation, thread CompeteThd2 uses the futex system call and enters the blocking state. Once thread CompeteThd1 completes the oncpu operation, thread CompeteThd2 obtains the CPU and performs the network write operation. Therefore, there is a high probability that lock contention occurs between threads CompeteThd1 and CompeteThd2. TCP network communication exists between the tcp-server thread and the CompeteThd2 thread. The CompeteThd2 thread cannot send network requests because it waits for lock resources. As a result, the tcp-server thread waits for read network requests most of the time.
topics
Supported System Call Events
The basic principles for selecting the system call events to be observed are as follows:
- Select events (such as file operations, network operations, and lock operations) that may be time-consuming and blocked. Such events usually involve access to system resources.
- Select events that affect the status of threads.
| Event/System Call | Description | Default Event Type | Extended Event Content |
|---|---|---|---|
| read | Reading or writing drive files or network resources, which may be time-consuming and blocked. | file | file.path, sock.conn, func.stack |
| write | Reading or writing drive files or network resources, which may be time-consuming and blocked. | file | file.path, sock.conn, func.stack |
| readv | Reading or writing drive files or network resources, which may be time-consuming and blocked. | file | file.path, sock.conn, func.stack |
| writev | Reading or writing drive files or network resources, which may be time-consuming and blocked. | file | file.path, sock.conn, func.stack |
| preadv | Reading or writing drive files or network resources, which may be time-consuming and blocked. | file | file.path, sock.conn, func.stack |
| pwritev | Reading or writing drive files or network resources, which may be time-consuming and blocked. | file | file.path, sock.conn, func.stack |
| sync | Synchronizing files to drives. The thread is blocked until the synchronization is complete. | file | func.stack |
| fsync | Synchronizing files to drives. The thread is blocked until the synchronization is complete. | file | file.path, sock.conn, func.stack |
| fdatasync | Synchronizing files to drives. The thread is blocked until the synchronization is complete. | file | file.path, sock.conn, func.stack |
| sched_yield | Proactively releasing the CPU for rescheduling. | sched | func.stack |
| nanosleep | Entering the sleep state. | sched | func.stack |
| clock_nanosleep | Entering the sleep state. | sched | func.stack |
| wait4 | Blocked. | sched | func.stack |
| waitpid | Blocked. | sched | func.stack |
| select | Blocked and waiting when no event arrives. | sched | func.stack |
| pselect6 | When no event arrives, the thread is blocked and waits. | sched | func.stack |
| poll | When no event arrives, the thread is blocked and waits. | sched | func.stack |
| ppoll | When no event arrives, the thread is blocked and waits. | sched | func.stack |
| epoll_wait | When no event arrives, the thread is blocked and waits. | sched | func.stack |
| sendto | Reading or writing network resources, which may be time-consuming and blocked. | net | sock.conn, func.stack |
| recvfrom | Reading or writing network resources, which may be time-consuming and blocked. | net | sock.conn, func.stack |
| sendmsg | Reading or writing network resources, which may be time-consuming and blocked. | net | sock.conn, func.stack |
| recvmsg | Reading or writing network resources, which may be time-consuming and blocked. | net | sock.conn, func.stack |
| sendmmsg | Reading or writing network resources, which may be time-consuming and blocked. | net | sock.conn, func.stack |
| recvmmsg | Reading or writing network resources, which may be time-consuming and blocked. | net | sock.conn, func.stack |
| futex | Usually indicates lock wait and thread blocking state. | lock | futex.op, func.stack |
Aggregated Events
Currently, tprofiling supports two types of system performance events: system call events and oncpu events. The oncpu event and some system call events (such as read/write) may be frequently triggered in a specific application scenario. As a result, a large number of system events are generated, which greatly affects the performance of the observed application program and the performance of the tprofiling probe.
To optimize performance, tprofiling aggregates multiple system events that belong to the same thread and have the same event name within a period of time (1s) into one event for reporting. Therefore, a tprofiling event actually refers to an aggregated event that contains one or more identical system events. Compared with a real system event, the meanings of some attributes of an aggregated event are changed as follows:
- start_time: start time of the event or the first event in an aggregated event.
- end_time: event end time, which is (start_time + duration) in an aggregated event.
- duration: event execution time or the accumulated execution time of all system events in an aggregation event.
- count: number of system events in an aggregated event. When the value is 1, an aggregated event is equivalent to a system event.
- Extended event attribute: extended attribute of the first system event in an aggregation event.
Introduction to L7Probe
L7Probe observes layer 7 traffic, covering common HTTP1.X, PG, MySQL, Redis, Kafka, HTTP2.0, MongoDB, RocketMQ, and encrypted traffic.
It covers node, container, and pod (K8s) scenarios.
Code Framework Design
L7Probe
   | --- included //Common header files

         | --- connect.h   // L7 connect object definition

         | --- pod.h   // Pod/Container object definition

         | --- conn_tracker.h   // L7 protocol tracker object definition

   | --- protocol // L7 protocol parsing

          | --- http // HTTP1.X L7 message structure definition and parsing

          | --- mysql // mysql L7 message structure definition and parsing

          | --- pgsql // pgsql L7 message structure definition and parsing

   | --- bpf // Kernel BPF code

         | --- L7.h   // BPF program for parsing L7 protocol types

         | --- kern_sock.bpf.c // Kernel socket layer observation

         | --- libssl.bpf.c   // openSSL layer observation

         | --- gossl.bpf.c   // GO SSL layer observation

         | --- cgroup.bpf.c // Pod life cycle observation

   | --- pod_mng.c // Pod/Container instance management (pod/container lifecycle awareness)

   | --- conn_mng.c // L7 Connect instance management (processing BPF observation events, such as Open/Close events and Stats statistics)

   | --- conn_tracker.c // L7 traffic tracker (tracking BPF observation data, such as data generated by system events such as send/write and read/recv)

   | --- bpf_mng.c // BPF program life cycle management (on-demand and real-time open, load, attach, and unload BPF programs, including uprobe BPF programs)

   | --- session_conn.c // Manages jsse sessions (records the mapping between jsse sessions and sock connections and reports jsse connection information).

   | --- L7Probe.c // Main program of the probe
Probe Output
| metrics_name | table_name | metrics_type | unit | metrics description |
|---|---|---|---|---|
| tgid | NA | key | NA | Process ID of l7 session. |
| client_ip | NA | key | NA | Client IP address of l7 session. |
| server_ip | NA | key | NA | Server IP address of l7 session. Remarks: In the K8s scenario, the cluster IP address can be converted into the backend IP address. |
| server_port | NA | key | NA | Server Port of l7 session. Remarks: In the K8s scenario, the cluster port can be converted to the backend port. |
| l4_role | NA | key | NA | Role of l4 protocol(TCP Client/Server or UDP) |
| l7_role | NA | key | NA | Role of l7 protocol(Client or Server) |
| protocol | NA | key | NA | Name of l7 protocol(http/http2/mysql...) |
| ssl | NA | label | NA | Indicates whether an SSL-encrypted l7 session is used. |
| bytes_sent | l7_link | gauge | NA | Number of bytes sent by a l7 session. |
| bytes_recv | l7_link | gauge | NA | Number of bytes recv by a l7 session. |
| segs_sent | l7_link | gauge | NA | Number of segs sent by a l7 session. |
| segs_recv | l7_link | gauge | NA | Number of segs recv by a l7 session. |
| throughput_req | l7_rpc | gauge | qps | Request throughput of l7 session. |
| throughput_resp | l7_rpc | gauge | qps | Response throughput of l7 session. |
| req_count | l7_rpc | gauge | NA | Request num of l7 session. |
| resp_count | l7_rpc | gauge | NA | Response num of l7 session. |
| latency_avg | l7_rpc | gauge | ns | L7 session averaged latency. |
| latency | l7_rpc | histogram | ns | L7 session histogram latency. |
| latency_sum | l7_rpc | gauge | ns | L7 session sum latency. |
| err_ratio | l7_rpc | gauge | % | L7 session error rate. |
| err_count | l7_rpc | gauge | NA | L7 session error count. |
Dynamic Control
Controlling the Scope of Observed Pods
- REST->gala-gopher.
- gala-gopher->L7Probe.
- L7Probe obtains related containers based on pods.
- L7Probe obtains the cgroup ID (cpuacct_cgrp_id) based on the container and writes the cgroup ID to the object module (the cgrp_add API).
- In the socket system event context, obtain the cgroup (cpuacct_cgrp_id) to which the process belongs. For details, see the Linux code (task_cgroup).
- The object module (the is_cgrp_exist API) can be filtered during observation.
Observation Capability Control
- REST->gala-gopher.
- gala-gopher->L7Probe.
- L7Probe dynamically enables or disables BPF observation capabilities (including the throughput, latency, trace, and protocol type) based on the input parameters.
Observation Points
Kernel Socket System Calls
TCP-related system calls
int connect(int sockfd, const struct sockaddr *addr, socklen_t addrlen);

int accept(int sockfd, struct sockaddr *addr, socklen_t*addrlen);

int accept4(int sockfd, struct sockaddr *addr, socklen_t*addrlen, int flags);

ssize_t write(int fd, const void *buf, size_t count);

ssize_t send(int sockfd, const void *buf, size_t len, int flags);

ssize_t read(int fd, void *buf, size_t count);

ssize_t recv(int sockfd, void *buf, size_t len, int flags);

ssize_t writev(int fd, const struct iovec *iov, int iovcnt);

ssize_t readv(int fd, const struct iovec *iov, int iovcnt);
TCP&UDP-related system calls
ssize_t sendto(int sockfd, const void *buf, size_t len, int flags, const struct sockaddr*dest_addr, socklen_t addrlen);

ssize_t recvfrom(int sockfd, void *buf, size_t len, int flags, struct sockaddr*src_addr, socklen_t *addrlen);

ssize_t sendmsg(int sockfd, const struct msghdr *msg, int flags);

ssize_t recvmsg(int sockfd, struct msghdr *msg, int flags);

int close(int fd);
Notes:
- The read/write and readv/writev operations may be confused with common file I/O operations. You can observe the security_socket_sendmsg function of the kernel to determine whether the FD is a socket operation.
- sendto/recvfrom and sendmsg/recvmsg are used by TCP and UDP. For details, see the following manuals.
- sendmmsg/recvmmsg and sendfile are not supported currently.
sendto manual: If sendto() is used on a connection-mode (SOCK_STREAM, SOCK_SEQPACKET) socket, the arguments dest_addr and addrlen are ignored (and the error EISCONN may be returned when they are not NULL and 0), and the error ENOTCONN is returned when the socket was not actually connected.otherwise, the address of the target is given by dest_addr with addrlen specifying its size.
If the value of dest_addr is NULL, TCP is used. Otherwise, UDP is used.
recvfrom manual: The recvfrom() and recvmsg() calls are used to receive messages from a socket, and may be used to receive data on a socket whether or not it is connection-oriented.
If the value of src_addr is NULL, TCP is used. Otherwise, UDP is used.
sendmsg manual: The sendmsg() function shall send a message through a connection-mode or connectionless-mode socket.If the socket is a connectionless-mode socket, the message shall be sent to the address specified by msghdr if no pre-specified peer address has been set. If a peer address has been pre-specified, either themessage shall be sent to the address specified in msghdr (overriding the pre-specified peer address), or the function shall return -1 and set errno to [EISCONN]. If the socket is connection-mode, the destination address in msghdr shall be ignored.
If the value of msghdr->msg_name is NULL, TCP is used. Otherwise, UDP is used.
recvmsg manual: The recvmsg() function shall receive a message from a connection-mode or connectionless-mode socket. It is normally used with connectionless-mode sockets because it permits the application to retrieve the source address of received data.
If the value of msghdr->msg_name is NULL, TCP is used. Otherwise, UDP is used.
libSSL API
SSL_write
SSL_read
Go SSL API
JSSE API
sun/security/ssl/SSLSocketImpl$AppInputStream
sun/security/ssl/SSLSocketImpl$AppOutputStream
JSSE Observation Scheme
Loading JSSEProbe
In the main function, l7_load_jsse_agent is used to load JSSEProbe.
Processes in allowlist (g_proc_obj_map_fd) are observed in polling mode. If the processes are Java processes, jvm_attach is used to load JSSEProbeAgent.jar to the processes. After the loading is successful, the Java process exports the observation information to the jsse-metrics output file (/tmp/java-data-<pid>/jsse-metrics.txt) at the specified observation point. For details, see JSSE API.
Processing JSSEProbe Messages
The l7_jsse_msg_handler thread processes JSSEProbe messages.
Processes in allowlist (g_proc_obj_map_fd) are observed in polling mode. If the processes have the corresponding jsse-metrics output file, the file is read by line, and JSSE read and write information is parsed, converted, and reported.
1. Parsing JSSE Read and Write Information
The output format of jsse-metrics.txt is as follows, from which the PID, session ID, time, read/write operations, IP address, port number, and payload information of a JSSE request is obtained:
|jsse_msg|662220|Session(1688648699909|TLS_AES_256_GCM_SHA384)|1688648699989|Write|127.0.0.1|58302|This is test message|
The parsed original information is stored in session_data_args_s.
2. Converting JSSE Read and Write Information
Information in session_data_args_s is converted to sock_conn and conn_data.
During conversion, the following hash maps are queried:
session_head: records the mapping between session IDs and sock connection IDs of JSSE connections. If the process IDs and the quadruplet information are the same, the session corresponds to the sock connection.
file_conn_head: records the last session ID of the Java process in case L7probe does not read the JSSEProbe output from the beginning of the request and cannot find session ID.
3. Reporting JSSE Read and Write Information
sock_conn and conn_data are reported to the map.
Usage
Deployment of External Dependencies

As shown in the preceding figure, the green parts are external dependent components of gala-gopher. gala-gopher outputs metric data to Prometheus, metadata and abnormal events to Kafka. gala-anteater and gala-spider in gray rectangles obtain data from Prometheus and Kafka.
Note: Obtain the installation packages of Kafka and Prometheus from the official websites.
Output Data
Metric
Prometheus Server has a built-in Express Browser UI. You can use PromQL statements to query metric data. For details, see Using the expression browser in the official document. The following is an example.
If the specified metric is gala_gopher_tcp_link_rcv_rtt, the metric data displayed on the UI is as follows:
gala_gopher_tcp_link_rcv_rtt{client_ip="x.x.x.165",client_port="1234",hostname="openEuler",instance="x.x.x.172:8888",job="prometheus",machine_id="1fd3774xx",protocol="2",role="0",server_ip="x.x.x.172",server_port="3742",tgid="1516"} 1Metadata
You can directly consume data from the Kafka topic gala_gopher_metadata. The following is an example.
# Input request
./bin/kafka-console-consumer.sh --bootstrap-server x.x.x.165:9092 --topic gala_gopher_metadata
# Output data
{"timestamp": 1655888408000, "meta_name": "thread", "entity_name": "thread", "version": "1.0.0", "keys": ["machine_id", "pid"], "labels": ["hostname", "tgid", "comm", "major", "minor"], "metrics": ["fork_count", "task_io_wait_time_us", "task_io_count", "task_io_time_us", "task_hang_count"]}
Abnormal events
You can directly consume data from the Kafka topic gala_gopher_event. The following is an example.
# Input request
./bin/kafka-console-consumer.sh --bootstrap-server x.x.x.165:9092 --topic gala_gopher_event
# Output data
{"timestamp": 1655888408000, "meta_name": "thread", "entity_name": "thread", "version": "1.0.0", "keys": ["machine_id", "pid"], "labels": ["hostname", "tgid", "comm", "major", "minor"], "metrics": ["fork_count", "task_io_wait_time_us", "task_io_count", "task_io_time_us", "task_hang_count"]}