chatglm-cpp User Guide
Introduction
chatglm-cpp is a ChatGLM model interface based on C/C++. It allows users to deploy and use open source models on CPU machines.
It supports the deployment of multiple open source Chinese LLMs, such as ChatGLM-6B, ChatGLM2-6B, and Baichuan-13B.
Software Architecture
The chatglm-cpp core architecture consists of two layers:
- Quantization layer: quantifies open source models to reduce the model size.
- Startup layer: starts a quantized model.
Features:
- Implemented in GGML-based C/C++.
- Accelerated CPU inference with int4/int8 quantization, optimized KV cache and parallel computing.
- Streaming generation with typewriter effect.
- Can run solely on CPUs, with no GPUs required
Installation Guide
Software and Hardware Requirements
Processor architecture: AArch64 and x86_64
OS: openEuler 23.09
Memory: at least 4 GB, depending on the size of different open source models.
Component Installation
Before using chatglm-cpp to deploy an LLM, install the chatglm-cpp software package. Before the installation, ensure that the openEuler yum source has been configured.
Install the package.
yum install chatglm-cppCheck whether the package is installed.
chatglm_cpp_main -h
If the help information is displayed, the installation is successful.
Usage Instructions
Using Directly
Install the chatglm-cpp software package.
yum install chatglm-cppDownload an open source LLM, such as ChatGLM-6B or ChatGLM2-6B. Use chatglm_convert.py to quantify the downloaded open source LLM.
python3 /usr/bin/chatglm_convert.py -i model_path/ -t q4_0 -o chatglm-ggml_1.binmodel_path indicates the path for storing the open source LLM, q4_0 indicates the quantization precision, and chatglm-ggml_1.bin indicates the name of the output model.
Start the model and start a dialog.
chatglm_cpp_main -m model_path -imodel_path indicates the path for storing the quantified model.
You can run the following command to view the command options:
chatglm_cpp_main -h
Using With a Container
Pull the container image.
docker pull hub.oepkgs.net/openeuler/chatglm_imageRun the container image and start a dialog.
docker run -it --security-opt seccomp=unconfined hub.oepkgs.net/openeuler/chatglm_image
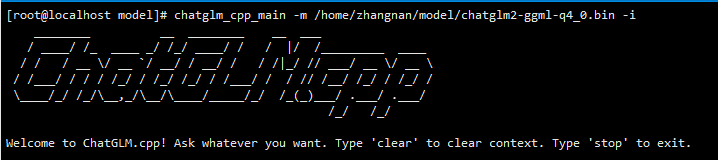
Normal Startup Page
Figure 1 shows the page after the ChatGLM2-6B model is started.
Figure 1 ChatGLM2-6B startup page
Specifications
This project allows you to deploy and infer LLMs on CPU-level machines. However, the model inference speed is hardware-dependent. If the hardware is set to the lowest settings, the inference speed may be slow, which can lower usage efficiency.
Table 1 lists reference inference speed in different machine configurations.
The table shows that Q4_0, Q4_1, Q5_0, and Q5_1 represent the quantization precision, while ms/token indicates the duration in milliseconds spent by each token inference, which is a measure of inference speed. A smaller value for ms/token indicates a higher inference speed.
Table 1 Test data of the ChatGLM-6B model inference speed
| ChatGLM-6B | Q4_0 | Q4_1 | Q5_0 | Q5_1 |
|---|---|---|---|---|
| ms/token (CPU @ Platinum 8260) | 74 | 77 | 86 | 89 |
| Model size | 3.3 GB | 3.7 GB | 4.0 GB | 4.4 GB |
| Memory usage | 4.0 GB | 4.4 GB | 4.7 GB | 5.1 GB |